Visual Scene Annotator
Reveal meaning, context, and structure behind the image
Visual Scene Annotator
Reveal meaning, context, and structure behind the image
展示内容
描述
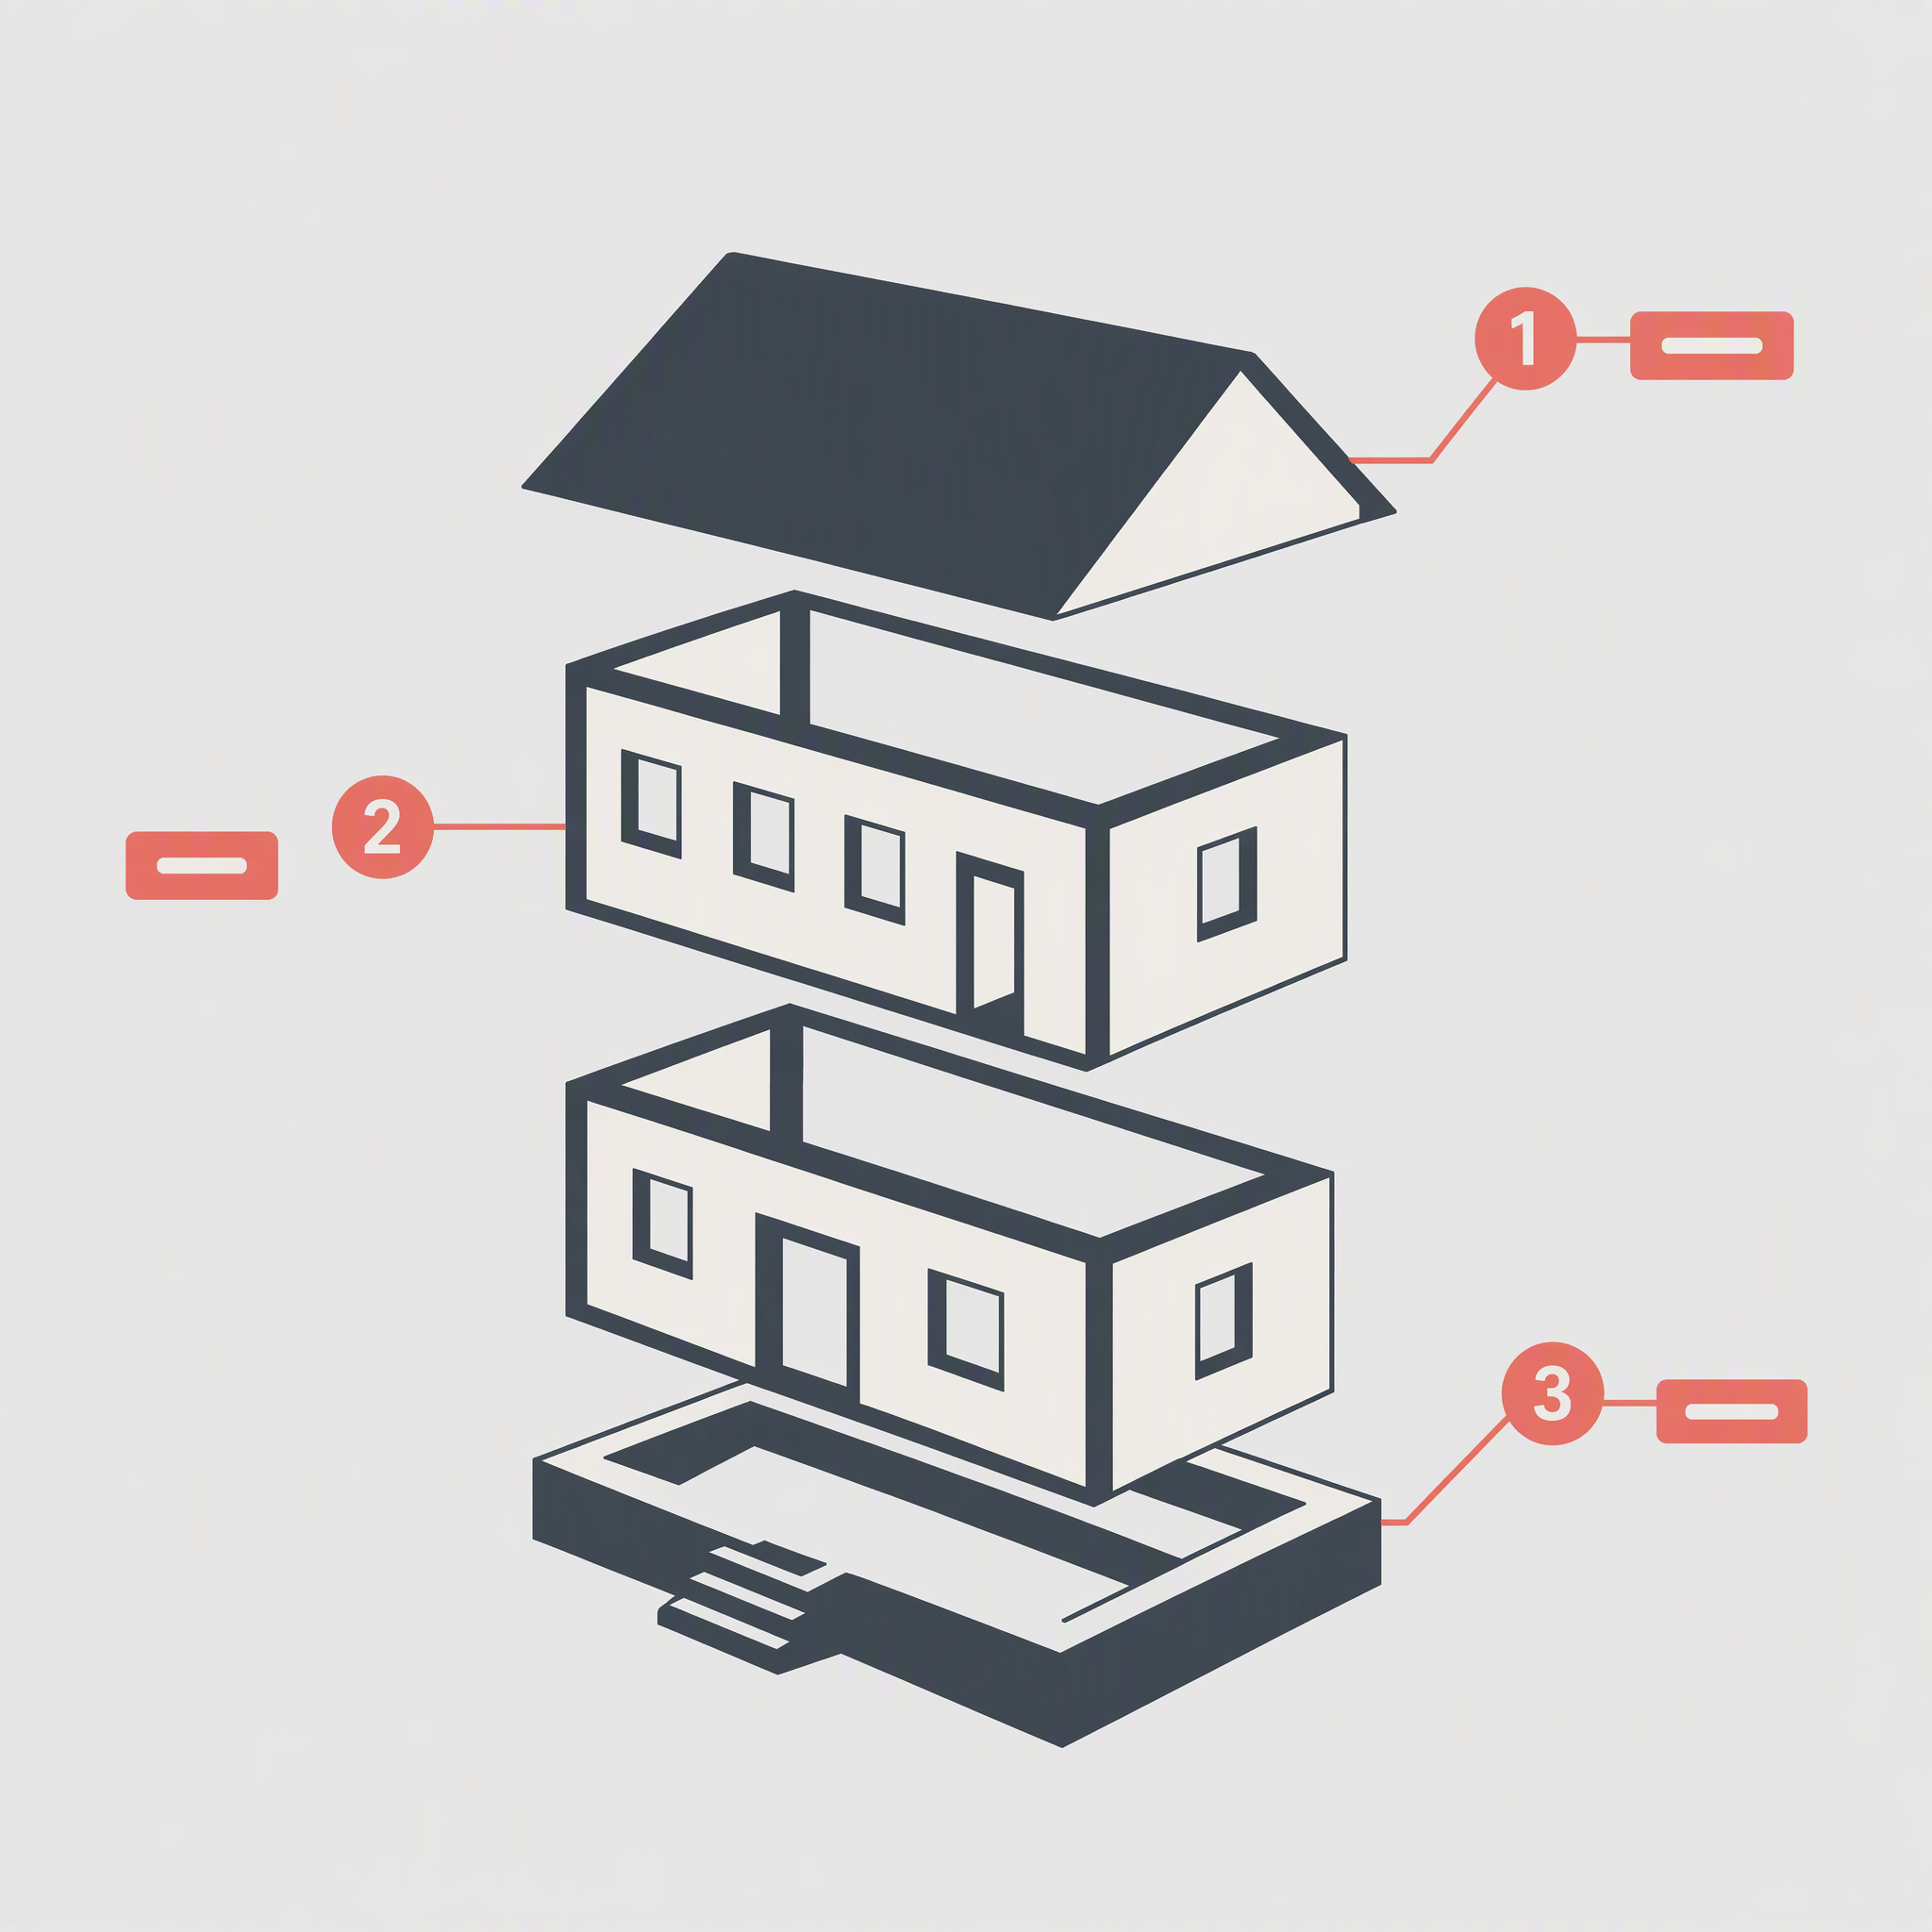
Turn a photo into a visual explanation of why its details matter. The Skill traces meaningful angles, shapes, joints, layers, and components on the original image, then explains their function, visual meaning, relevant background, and possible design influences. When useful, it adds a clearly labeled conceptual cutaway or exploded view beside the photo to show how the subject may be structured inside. Observed facts, verified context, and visual inference remain clearly separated.
相关技能
查看全部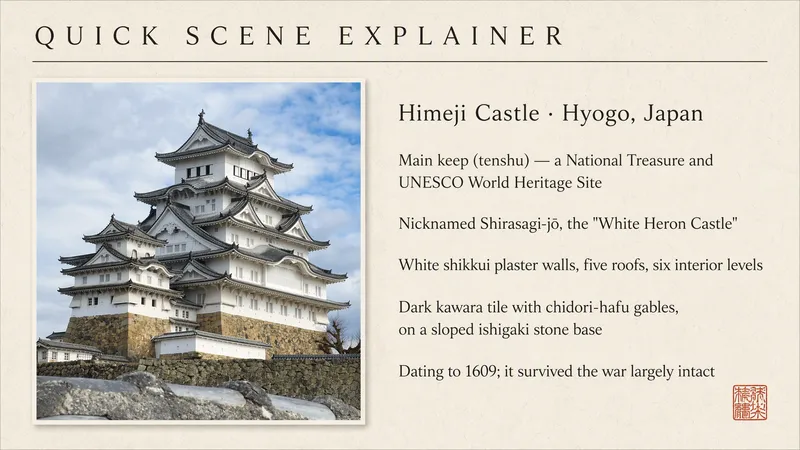
Quick Scene Explainer
Get a concise, text-only explanation of a photo or screenshot without waiting for image generation. It identifies the relevant object, interface, sign, diagram, or visible structure; refers to parts by their position in the image; answers the user's immediate question; and clearly marks anything it cannot confirm. Designed for quick mobile use, weak connections, and situations where the user needs an answer now rather than a redesigned image.
What is it ?
Turn a user's uploaded everyday photo into an immersive language scene with localized controls, object labels, pronunciation, a bilingual passage, typing practice, an overview, and a find-the-object game. Do not use for ordinary image descriptions or static word lists.
 图片
黏土等距解释图工作室
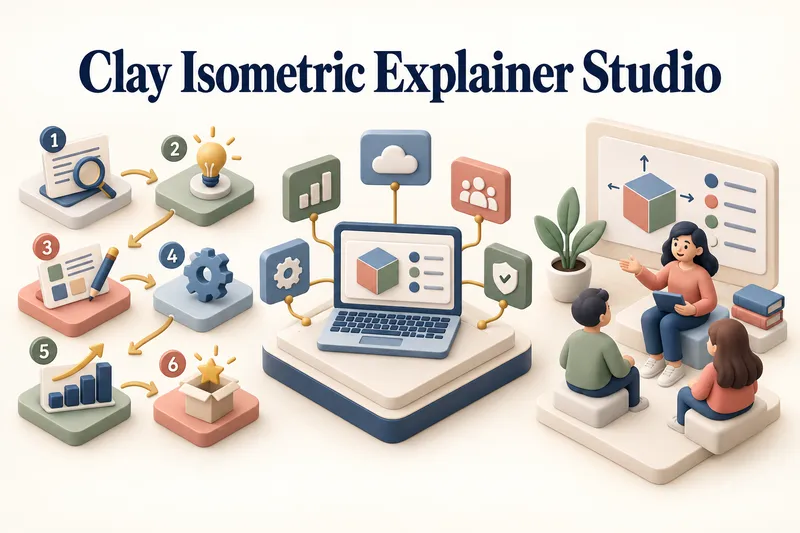
将任何主题转化为清晰、令人印象深刻的视觉说明。 黏土等距解释图工作室可将产品、流程、服务、系统和教育主题,转化为精致的混合 3D 黏土与等距视觉内容。 你只需提供一个主题即可开始。工作室会进行聚焦的研究概览,提炼核心信息,推荐最清晰的视觉方向,并逐步引导你完成创作流程。 它会搭建信息架构,将每个观点对应到具体的视觉对象,定义统一的风格系统,并准备完整的制作提示词。标题、编号阶段、信息卡片、标签和简短说明都会在图像生成过程中直接规划并加入。 你可以选择解释场景、流程图、产品功能板、教育视觉内容,或一组风格统一的 3–5 件视觉系列。静态图像确认后,还可以选择将其转化为简短的图生视频动画,加入细微的物体运动、自然的黏土角色动作,或通过编号阶段引导视觉焦点。 适用于演示文稿、网站、社交媒体帖子、海报、PDF 页面、产品传播、入职培训和学习材料。 不适用于没有解释目的的装饰性 3D 场景、随机视觉元素、图像中的大段文字,或最终可编辑的设计文件。
信息
- 版本
- v15
- 更新时间
- 运行积分
- 按实际用量
- 模型
- 自动选择