Neon Genesis Evangelion Style
Bilingual prompts for angular mecha stills
Neon Genesis Evangelion Style
Bilingual prompts for angular mecha stills
Showcase
Description
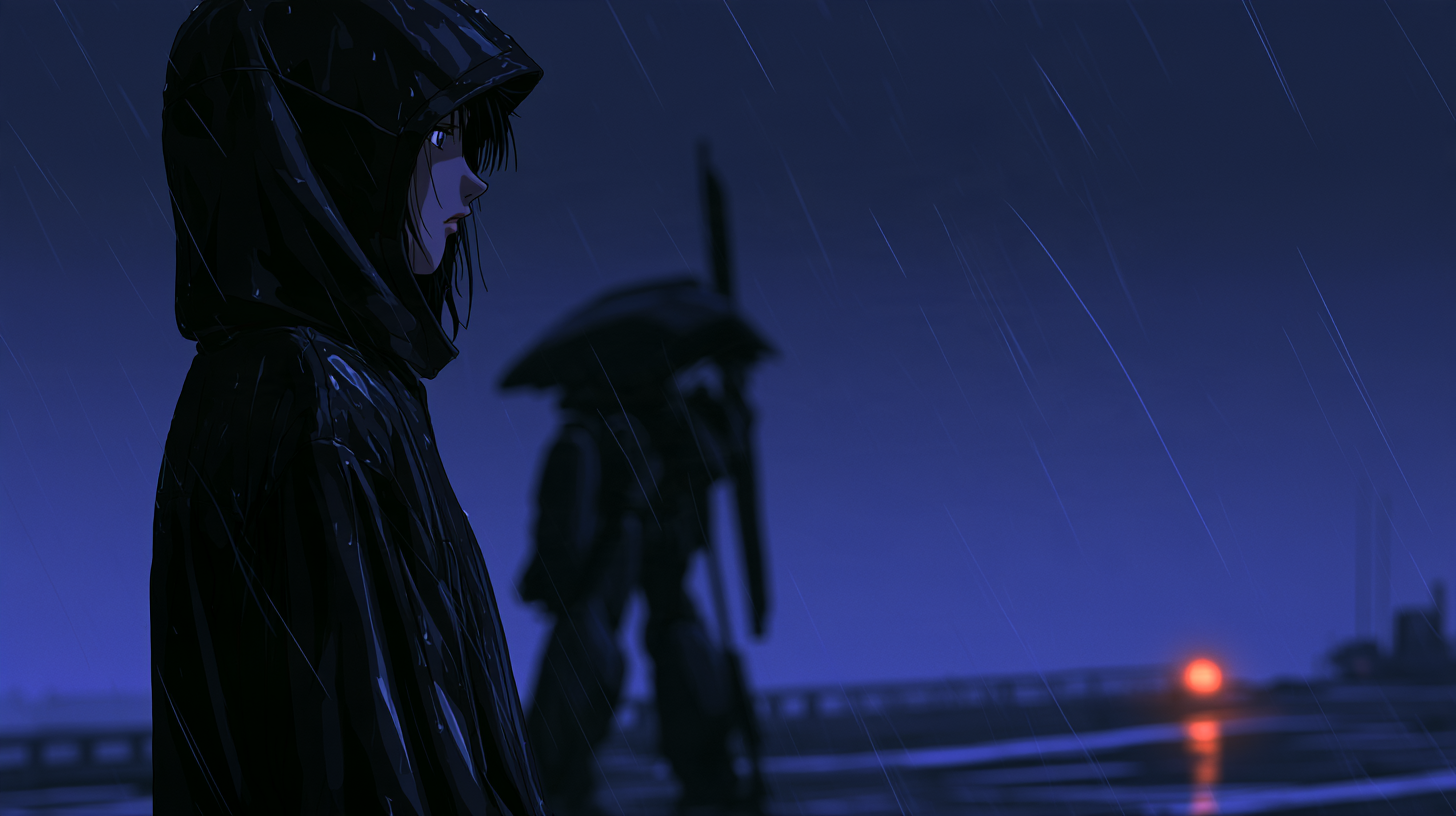
Transform characters, mecha, still lifes, or architectural scenes into sharp, slender visual prompts suited to still-image generation. Empty-space geometry, broad color fields, hard-edged shadows, and clear scale relationships work together to create distinctive compositions. Whether it is a character in an empty corridor, machinery framed by architecture, or mecha emphasizing points of contact and support, the style preserves the number of subjects, actions, objects, proportions, and specified colors while transferring the visual language. You will receive Chinese composition guidance, English Midjourney prompts, and native Chinese prompts for ImageGen, suitable for single images or series work that requires changes and contact relationships to remain consistent frame by frame. The style emphasizes negative space, slender forms, hard geometry, and cool, stark warning colors, avoiding a shift toward dense industrial cyberpunk or dependence on neon elements. By default, it writes prompts only and does not generate images.
Recommended by
淡苍
Why we love this skill
Distinctive mecha still frames built from slender forms, empty-space geometry, broad color fields, and clear scale relationships—without relying on giant robots or neon overload.
Best for
Visual creators turning characters, mecha, or architectural scenes into sharp, slender prompts for geometric still images with empty space.
How to use this Skill
Provide your input
Provide a character, mecha, still life, or architectural scene, including the number of subjects, actions, objects, proportions, colors, and whether it is a single image or series.
Run the Skill
Transform the subject into a still-image aesthetic built from empty-space geometry, slender forms, broad color fields, and hard shadows while preserving explicit constraints.
Review your result
Receive Chinese composition guidance, English Midjourney prompts, and Chinese ImageGen prompts. By default, this skill writes prompts only and does not generate images.
Related Skills
View all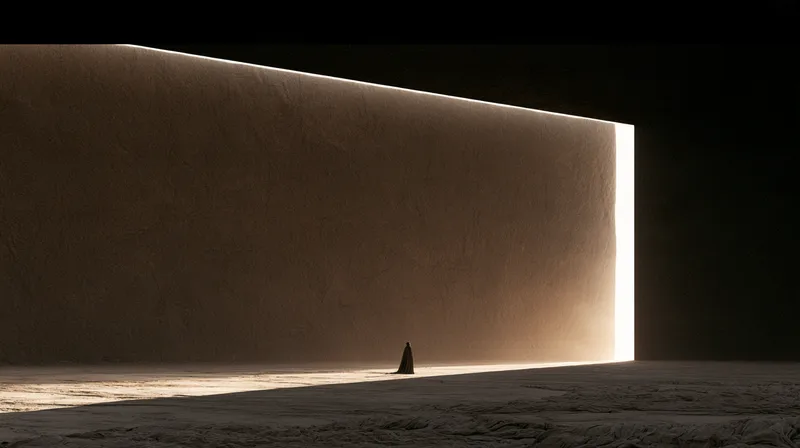 Image
Desert Megastructure Aesthetic
Turn people, objects, cities, interiors, or other suitable subjects into ready-to-use minimalist still-image prompts in a desert megastructure style. The skill preserves the user’s specified subject, number of people, actions, contact relationships, and scene function, while using low-saturation sand and mineral gray, monolithic wedge-shaped geometric megastructures, hard sunlight, vast pure-dark surfaces, and extreme contrasts of scale to create a silent, restrained, architectural image. It does not rely on a film title as a substitute for specific descriptions of lighting, materials, and composition. You’ll get a clear compositional intent, native Chinese ImageGen prompts, and English Midjourney prompts. You can also reduce the output to a single-platform version as needed. This is suitable for single stills, consistently styled image sets, and correcting common deviations such as oversaturated colors, overly dense machinery, unbalanced scale, or visual noise. The visual language can also be applied to city and interior subjects without forcing in a desert. When you request actual image generation, the skill can additionally check character visibility, contact relationships, style anchors, and consistency across images.
Light-and-Dark Zen Framing
Turn your written concept or reference image into a “light-and-dark framed Zen” scene: dark architecture or structures form a natural frame in the foreground, leaving an open, bright space within. A person or subject stands in the light at a small scale, as a silhouette or in muted colors, while crisp, elongated geometric shadows reinforce a sense of order and solitude. The overall style emphasizes high-contrast lighting, near-black shadows, restrained colors, ample negative space, and a tranquil, minimalist visual experience. It is suited to creating a meditative, ceremonial, and East Asian Zen atmosphere, while also extending to modern urban or Western classical settings. During generation, the architectural context is naturally matched to the subject’s identity, era, and cultural character—for example, a monk in a Zen temple corridor, a scholar in an academy, a samurai in a Japanese garden, a historical figure in a classical courtyard, or an urban professional in a glass-curtain-wall space—while preserving any scene you explicitly specify. For uploaded images, the composition can be reconstructed around a dark frame, bright area, subject in light, and long shadows while preserving the subject’s identity and approximate pose as much as possible. If the original image lacks spatial structure suitable for reconstruction, the style will not be forced onto it. Suitable for text-to-image, image-to-image, and style transfer; not suitable for highly saturated color images, standard black-and-white filters, or photo-realistic commercial portraits.
 Image
Stephen Chow Street Comedy
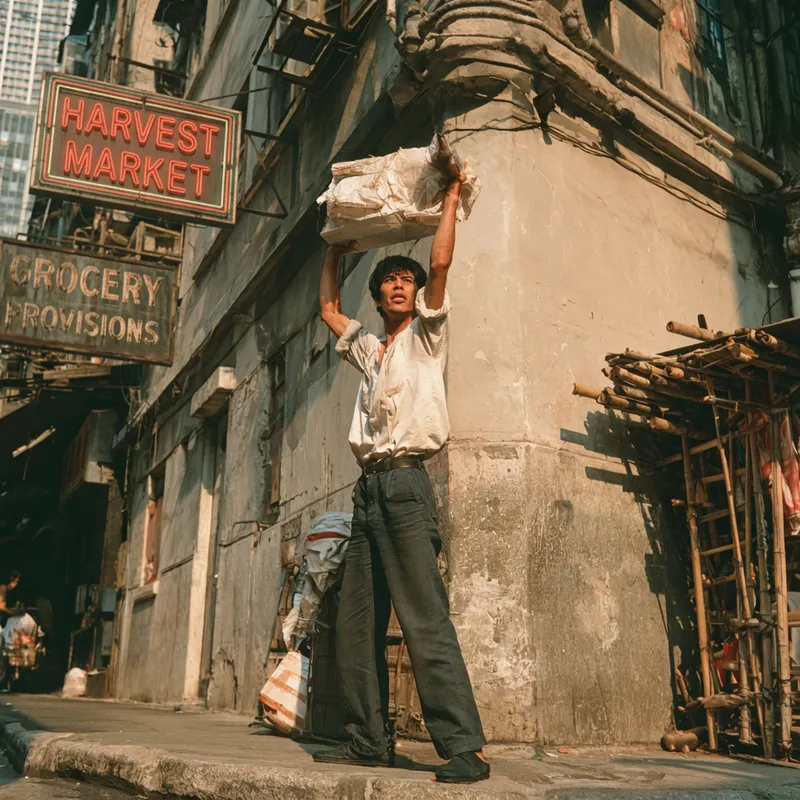
Turn a visual concept or a reference image with clearly defined character roles into live-action comic-comedy still-image prompts for Chinese ImageGen and English Midjourney. It focuses on bright, realistic everyday street spaces, using clear medium-wide or full-body compositions so character actions, points of contact with the ground, prop relationships, and group reactions are easy to understand. It is suited to everyday contrasts and exaggerated yet believable physical performances, especially the street-level live-action comedy atmosphere of *Kung Fu*, rather than 2D cartoons, actor imitation, or bizarre body transformations. Based on your subjects, number of people, actions, reference characters, and aspect-ratio requirements, the prompts preserve ordinary buildings, old walls, wooden objects, and restrained yet lively everyday colors. Repeated poses, spacing between groups, and subtle changes in perspective and scale add comic rhythm. Interactions such as holding, leaning, and watching are kept with clear force relationships and solid physical structure wherever possible, avoiding collaged figures, intersecting props, and distorted perspective. Whether you need a single concept image, a continuous sequence, or character and composition transfer from a reference image, you can get platform-specific prompts ready to copy and use. Simply specify the target platform to generate the corresponding version.
Information
- Version
- v2
- Last updated
- Runtime credits
- Usage-based
- Models
- Auto
- Use cases
- Images & design
- What you get
- Prompt