Video Transcription
Video Transcription
Showcase
Description
Transcribe local video or audio into timestamped SRT subtitles and plain text, preferring local processing and supporting configured remote ASR services with consent.
Related Skills
View all Write
Audio to Draft
Turn an audio file, voice note, spoken video, or transcript into one coherent editable draft. Missing speech text is transcribed automatically, with background continuation when needed, so the user does not have to return to resume the workflow.
 Research
Audio to Tasks & Decisions
Turn an audio file or transcript into a concise editable record of decisions, tasks, owners, dates, blockers, and open questions. Missing speech text is transcribed automatically, with background continuation when needed, before any optional Agent actions are proposed.
 Research
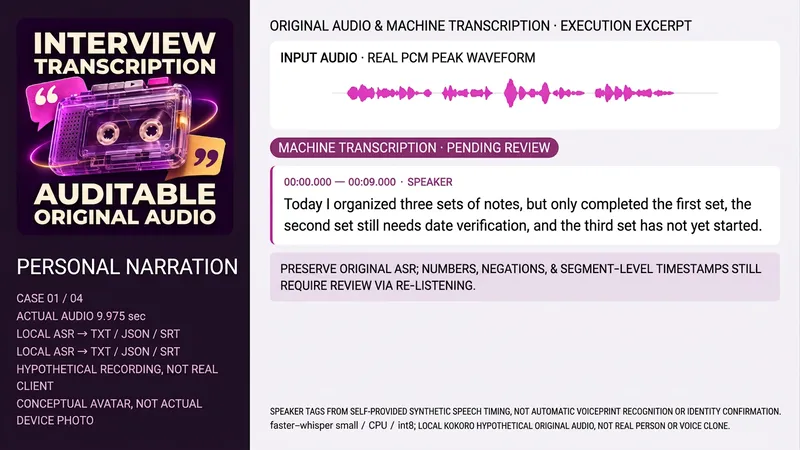
Interview Audio Transcriber
Ideal for anyone needing to organize authorized interview, meeting, or lecture recordings. Provide the source file, language, purpose, existing transcript, or trusted speaker time mapping. It cannot confirm identities by voice alone or treat scripts as actually heard content. Retains original audio and hash, reads duration and tracks, performs actual ASR, organizes by real timeline, labels anonymous speakers when evidence permits, cross-checks numbers, negatives, names, and doubts against the original audio, and delivers TXT, JSON, SRT, and coverage notes. Machine drafts, proofed drafts, and summaries are separated; unclear parts remain pending review without forced filler words. Untranscribed items are clearly noted if audio or ASR tools lack them. Includes a complete local Python assistant with Python3, FFmpeg/FFprobe, faster-whisper, and pre-configured small cache using CPU/int8 and local_files_only without auto-downloading weights. Trusted speaker-maps provide start/end and anonymous labels for window-based transcription and time mapping, defaulting to unknown when absent. The assistant does not perform automatic voice separation or identity recognition, and no weights, accounts, or keys are bundled. Four test samples include self-prepared Chinese monologue, Chinese dialogue, English lecture intro, and Chinese meeting, totaling about 40.875 seconds. Final audio uses locally synthesized Kokoro-82M fixed version under Apache-2.0 (zf_xiaobei, zm_yunjian, af_heart) and is not real or cloned voice. Models, voices, and samples are not distributed with the package. All four tests generate TXT/JSON/SRT via real ASR, with speakers derived from provided synthesized timing rather than diarization. First-draft divergences remain pending review rather than altered arbitrarily. Waveforms come from actual PCM peaks, not decorative visuals. Text organization is recommended for GPT, with ASR subject to actual tools. No OpenAI transcription APIs or upstream CLI are called locally. The avatar is an ImageGen concept visual without model return or Image2 claims. YouMind platform tools, caches, downloads, and bindings consume no test points, subject to environment confirmation. Transcription and speaker organization do not guarantee dependency-free execution post-installation. The 299 points cover the installation price only, excluding models, APIs, or third-party services, and will not auto-purchase or upload unknown tracks to external services. Zero errors, full recognition of any accent, noise, or overlap, legal identification, time efficiency, or commercial results are not promised. Independent audio proofing is pending, without claiming verified transcripts.
Information
- Version
- v2
- Last updated
- Runtime credits
- Usage-based
- Models
- Auto
