Nonverbal Insight Analyzer
Read faces, body language, and hidden social cues
Nonverbal Insight Analyzer
Read faces, body language, and hidden social cues
Showcase
Description
Go beyond obvious labels like “happy,” “angry,” or “confident.” Nonverbal Insight Analyzer examines the small visual details that shape how a person or interaction is perceived: facial tension, gaze direction, eyelids, mouth and jaw, head position, shoulders, posture, hands, body orientation, physical distance, asymmetry, and contradictions between signals. Before the analysis begins, it asks only a few relevant context questions so the image is not interpreted in isolation. A candid moment, posed portrait, conversation, workplace scene, or relationship dynamic can carry very different meanings. The Skill then connects individual clues into a coherent reading rather than simply listing them. It looks for supporting signals, competing explanations, and details that may be easy to miss—such as a relaxed face paired with tense hands, a smile that is not supported by the rest of the body, or a gaze direction that conflicts with torso orientation. When requested, the report can also include traditional physiognomy perspectives such as Turkish/Ottoman kıyafetname and firaset traditions, Western physiognomy, Chinese Mian Xiang, or a cross-cultural comparison. Historical interpretations are kept clearly separate from modern nonverbal analysis and are sourced when research is available. The final report is designed to be deep but easy to read: clear interpretation, subtle clues, alternative explanations, important contradictions, and the strongest takeaways—without turning the result into an academic paper or a shallow emotion label.
Related Skills
View all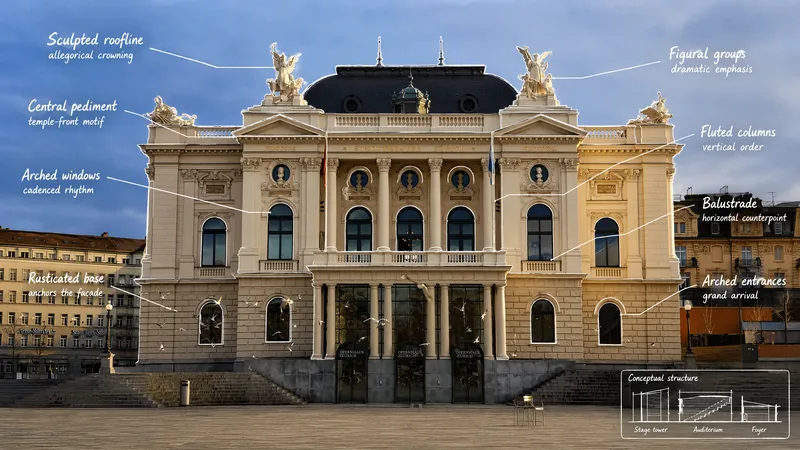 Image
Visual Scene Annotator
Turn a photo into a visual explanation of why its details matter. The Skill traces meaningful angles, shapes, joints, layers, and components on the original image, then explains their function, visual meaning, relevant background, and possible design influences. When useful, it adds a clearly labeled conceptual cutaway or exploded view beside the photo to show how the subject may be structured inside. Observed facts, verified context, and visual inference remain clearly separated.
Create cinematic portraits
Describe a person and a scene — who they are, what they are wearing, where they stand, and the light or mood — and this skill composes the prompt and generates a set of cinematic, photorealistic portrait images. Any missing detail is filled with a tasteful, coherent default so a usable result always comes back. Works for any subject, culture, wardrobe, or environment.
 Research
Signal Room: Interview Synthesis
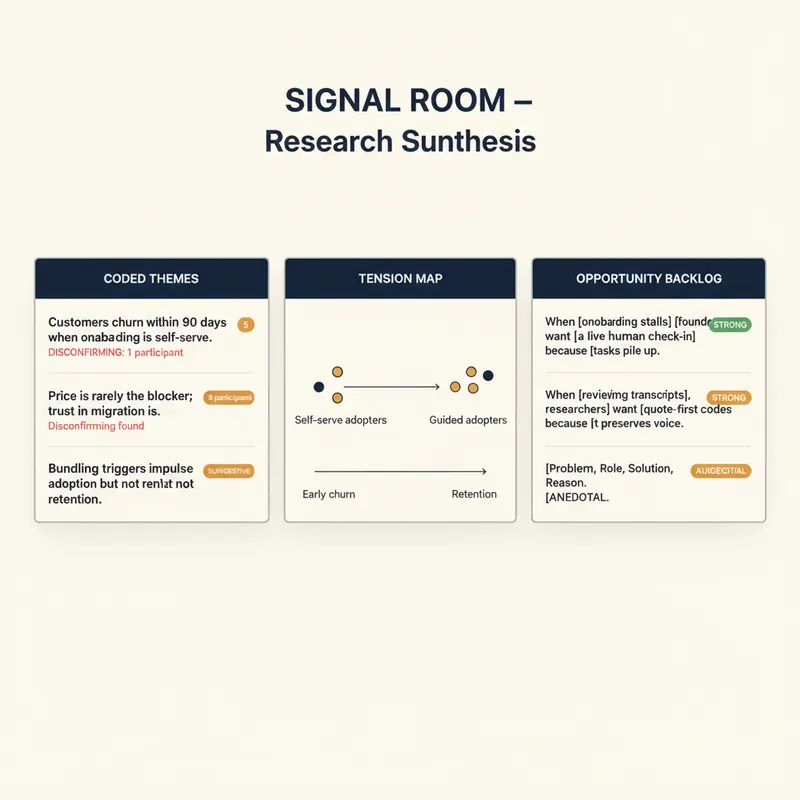
YouMind already transcribes your calls, interviews and podcasts. Signal Room is what happens next. Drop in one transcript or twenty and get back a research synthesis an actual analyst would sign: coded themes, verbatim evidence with timestamps, the places people disagree, and a ranked answer to the decision you are trying to make. The method is real qualitative practice, not summarisation: • Open coding that works quote-first — no quote, no code — with codes named in the participant's own words rather than analyst jargon • Every code tagged Behaviour, Belief or Wish, because "I would definitely pay for that" is not the same class of evidence as "I paid for that last month" • Themes stated as falsifiable sentences, with strength counted in participants rather than quotes, and disconfirming evidence hunted for on purpose • A tension map showing where your participants genuinely split and what predicts which side they fall on • An opportunity backlog written as "when [situation], [who] wants [outcome] because [reason]", each rated Strong, Suggestive or Anecdotal • A direct answer to your decision question, with a stated confidence level and what would change it • The three questions this round could not answer, and who to interview next Guardrails that matter: it never invents or polishes a quote, it refuses to report percentages on fewer than twelve participants, it pseudonymises participants by default, and it will tell you to your face when n=1 means you have a hypothesis rather than a finding. For product managers, UX and market researchers, journalists, consultants, founders doing customer discovery, and anyone sitting on hours of recordings and no findings.
Information
- Version
- v9
- Last updated
- Runtime credits
- Usage-based
- Models
- Auto
